Do AI Confabulate or Hallucinate?
 |
To anyone who has experimented with generative AI systems or large language models (LLMs), it’s pretty clear that these models are capable of producing content that sounds both perfectly accurate and fully confident. AI sometimes produces false information with surprising fluency, whether it is writing a scientific citation, misquoting a historical event, or writing logical steps that seem completely plausible.
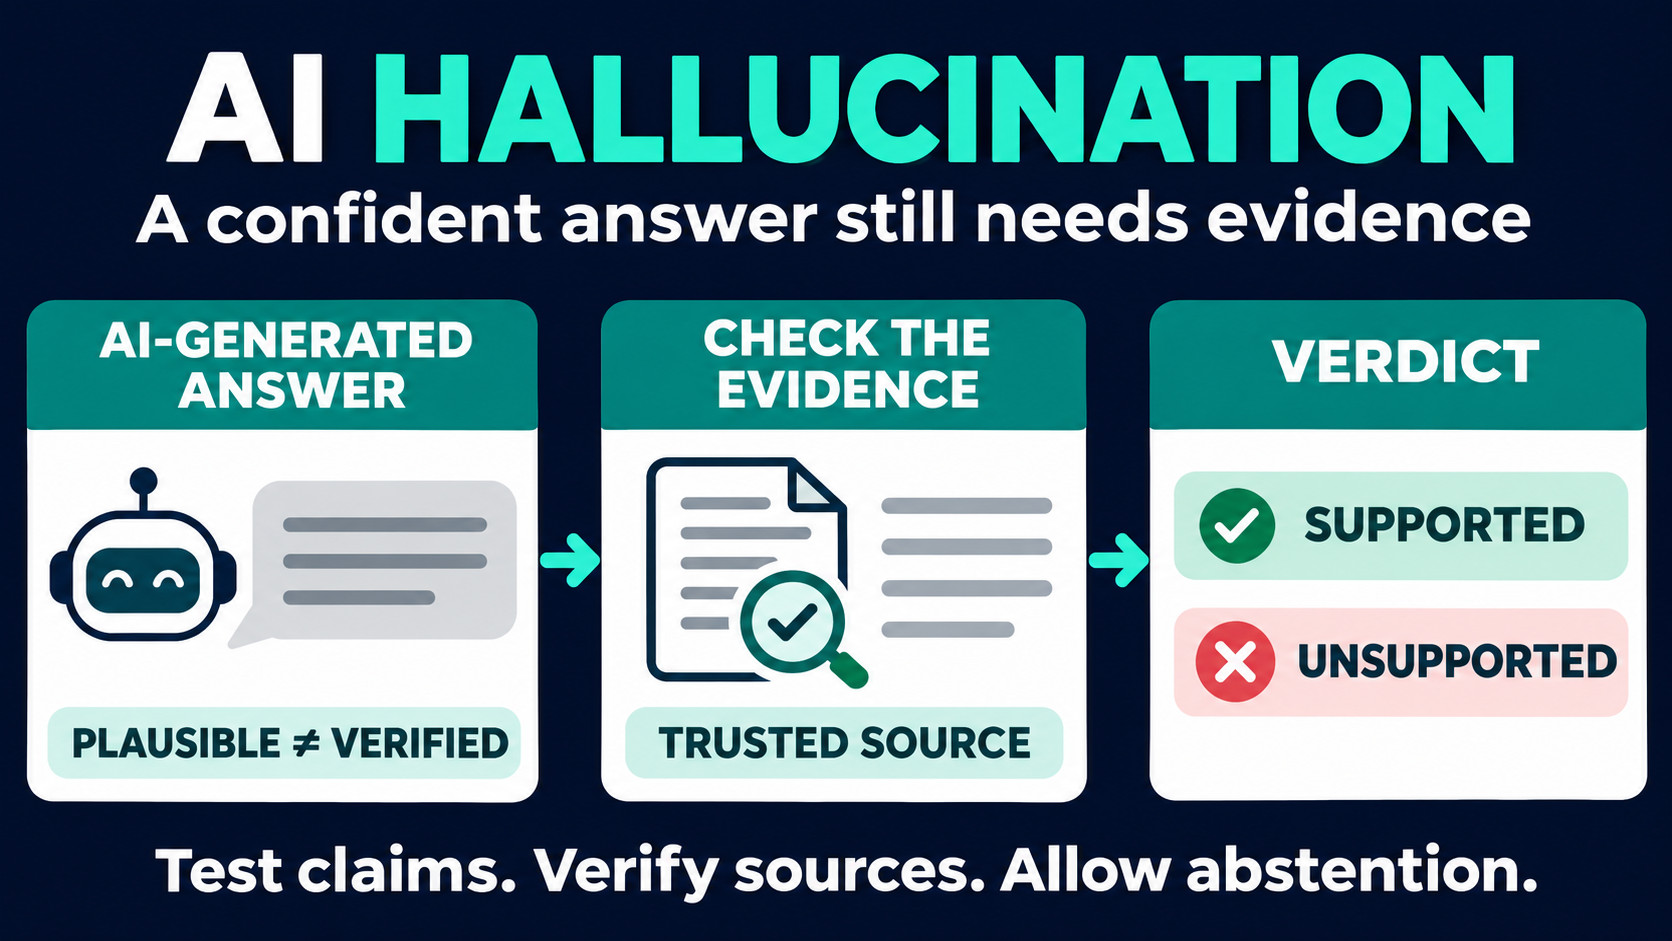
People commonly call these errors AI hallucinations. Some technical guidance, including NIST’s Generative AI Profile, uses confabulation for the same broad phenomenon: a system confidently produces false, unsupported, or internally inconsistent content. Neither term implies that an AI system has human perception or intent. The practical question is how teams can detect, measure, and reduce unsupported outputs.
| Key Takeaways: |
|---|
|
The blog covers ideas behind AI confabulation and hallucinations, their differences, the reasons behind AI models’ hallucinations, and how organizations can reduce these issues in operational systems. In addition, we will also include examples, troubleshooting techniques, and the most recent developments in AI safety and hallucination mitigation.
What is an AI Hallucination?
- Invented facts, dates, or scientific claims
- Fabricated quotes, references, or URLs
- Logical reasoning that appears coherent but is fundamentally incorrect
- Incorrect summaries that distort source content
LLMs do not mean to mislead when they produce this type of false information. They only use their training patterns to forecast the next most possible word sequence. In different terms, an AI hallucination is a self-assured error based on probability rather than intention or perception. For more on evaluating hallucinations and reliability, read LLM Hallucination and Reliability Testing.
What Does AI Confabulation Mean?
In psychology, confabulation describes the production of false or distorted memories without a conscious intention to deceive. In AI discussions, the term is used for confidently generated false or unsupported content. NIST uses “confabulation” in its Generative AI Profile and notes that these outputs can include false claims, unsupported citations, and content that conflicts with the prompt or earlier statements.
The term can help avoid suggesting that a model literally sees or experiences something. However, “confabulation” is not a universally accepted replacement for “hallucination.” Both terms are in use, and readers may encounter either one in research, product documentation, or public discussion.
A practical convention for this article is to use “hallucination” for the familiar user-facing term and “confabulation” when discussing the same errors in technical or governance contexts. The important question is whether the output is supported by reliable evidence.
Do AI Systems Confabulate or Hallucinate?
Which term is more accurate?
| Term | Pros | Cons |
|---|---|---|
| AI Hallucination | Widely understood; intuitive metaphor | Implies senses, perception, and experience, which AI does not have |
| AI Confabulation | Mechanistically accurate; matches gap-filling behavior | Less common; less familiar to non-experts |
So, do AI hallucinate or AI confabulate? The extent to which you interpret the terms will influence the answer.
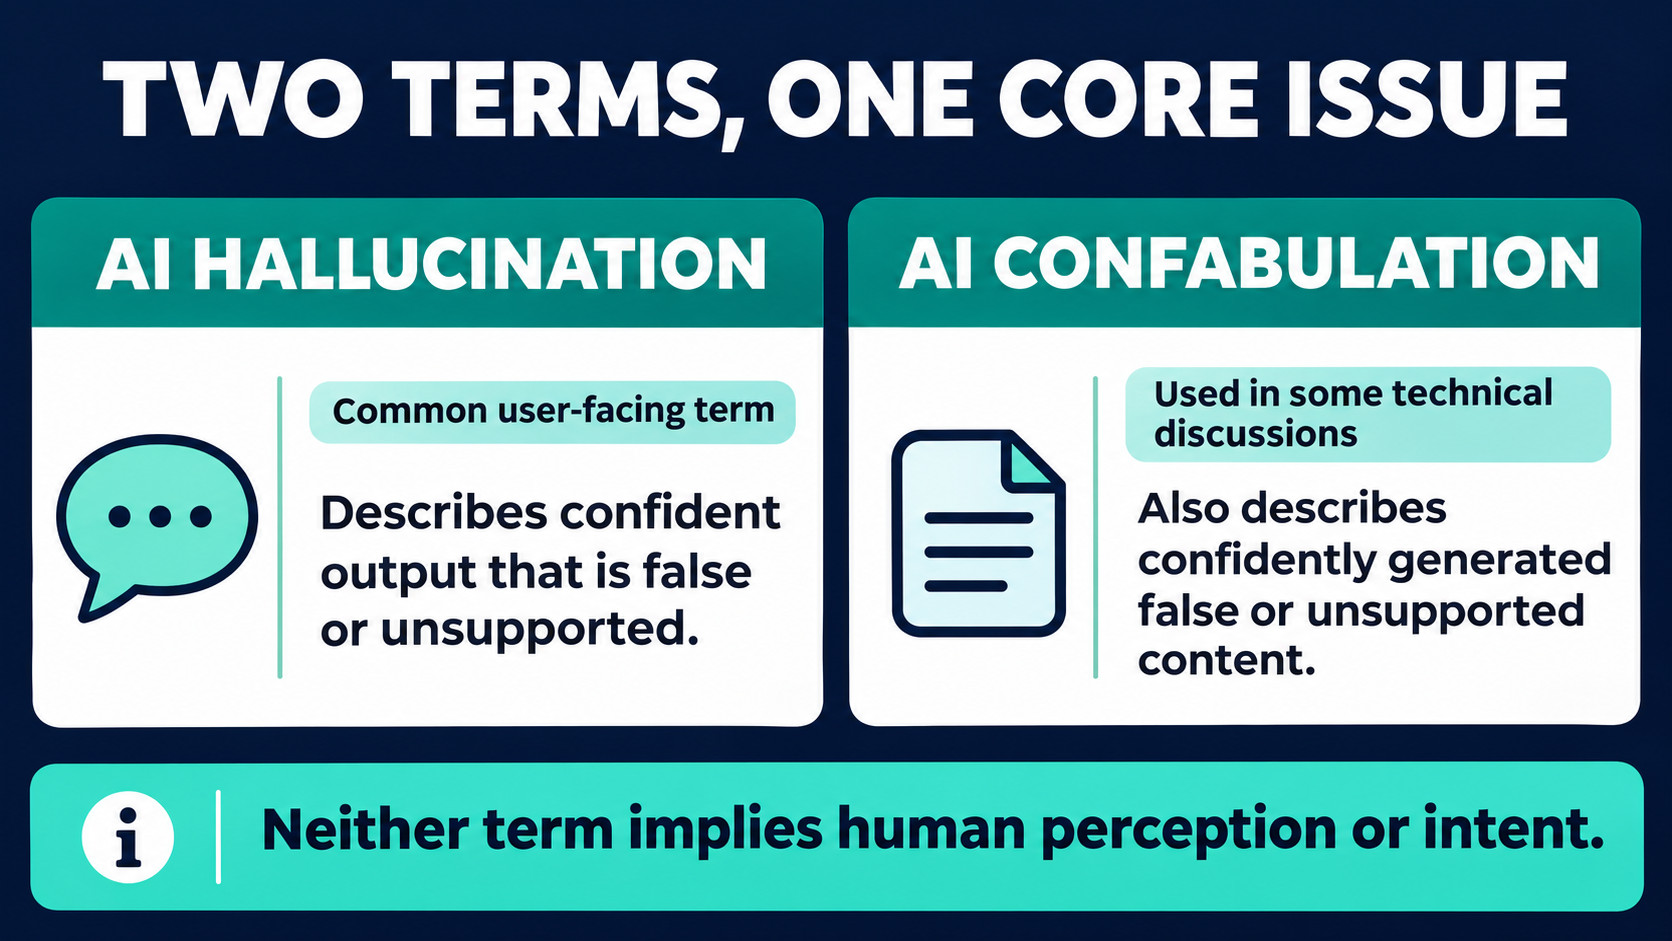
While “confabulation” prevents implying that AI has consciousness or sensory experience, both terms point to LLM hallucinations or AI false results.
- “Model Confabulation” when discussing the mechanics
- “AI Hallucination” when discussing user-facing behavior
What Causes AI Hallucinations?
There is no single cause. Errors can arise from the model, its data, the prompt, retrieval and tools, or the way the complete system is designed.
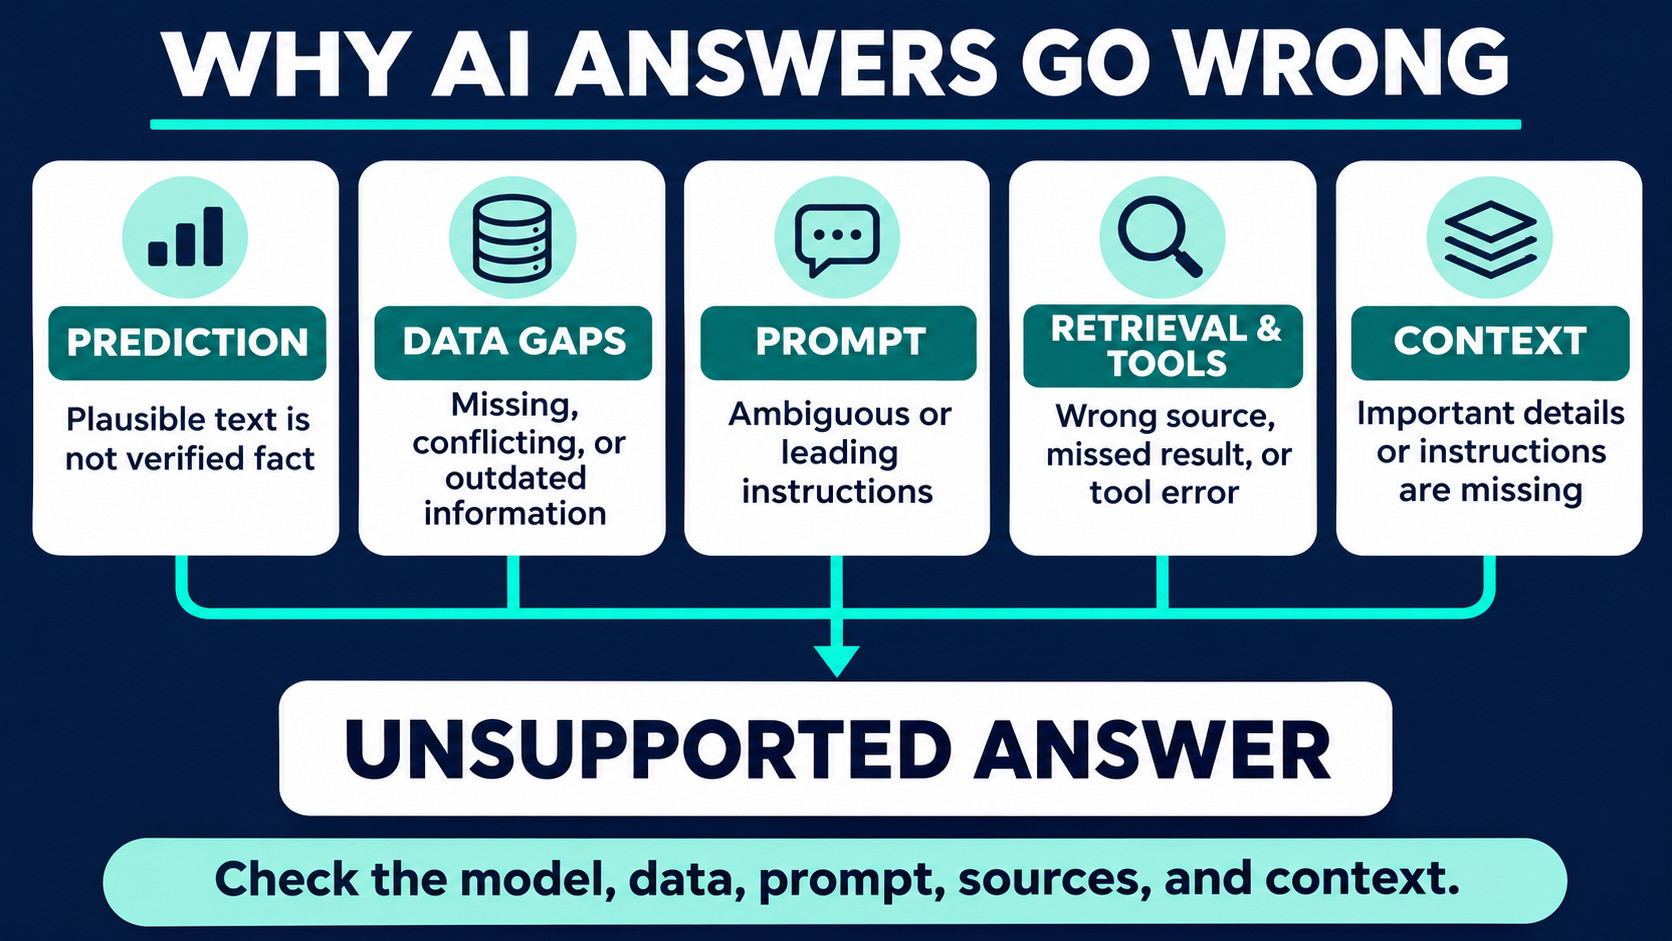
- Prediction without built-in verification: A language model generates likely text based on learned patterns. Unless the system is connected to a dependable source or verification step, generating a plausible answer is not the same as checking that answer against reality.
- Gaps, conflicts, and stale information: Training data and connected knowledge sources can be incomplete, contradictory, low quality, or out of date. A model can reproduce those weaknesses or combine fragments in a way that creates a false claim.
- Overgeneralization: A model may extend a familiar pattern to an unfamiliar case or apply a rule to an exception where it does not hold.
- Ambiguous or leading prompts: A vague question can have several interpretations. A prompt that pressures the model to answer despite missing evidence can also encourage unsupported completion.
- Retrieval and tool failures: Search, databases, and APIs can improve access to information, but the system may retrieve irrelevant or stale material, miss the right document, misread a passage, or cite a source that does not support its claim.
- Context and instruction problems: Long conversations can exceed the information the system can use effectively. Conflicting instructions or missing context can also lead to answers that do not follow the intended task or source. Read: Top 10 OWASP for LLMs: How to Test?
Examples of AI Hallucinations
- Fabricated Citations: A model may invent fabricated:
- Journal titles
- Page numbers
- DOIs
- Nonexistent research findings
- False logical chains
- Invented Precedents: LLMs may create fictitious court cases, an issue that has already had legal consequences.
- Incorrect Mathematical Reasoning: LLMs may implement formulas incorrectly or generate steps that seem to be correct but generate incorrect outcomes.
- Fictitious Biographies or Events: When enquired about unfamiliar subjects, models often confabulate details about people or places.
These explain why, in delicate scenarios like healthcare, law, or scientific research, AI reliability concerns need to be taken seriously.
AI Error Types and Where Hallucination Fits in
- Factual errors (hallucinations/confabulations)
- Reasoning errors
- Instruction-following errors
- Ambiguity errors
- Bias-induced errors
- Context truncation errors
- Probability-based overgeneralization
While hallucinations belong to a specific category of factual errors, they often interact with issues with reasoning and generalization.
AI Hallucinations vs. Human Error: A Useful Comparison
While human errors and AI hallucinations may seem similar at first glance, their root causes are quite different. Errors are due to cognitive biases, memory restrictions, or misperception. On the other hand, AI confabulation is due to statistical prediction rather than misinterpretation. This difference is important because AI false outputs arise from the underlying model architecture and training data. This needs a technical rather than psychological solution, whereas human errors are often connected to emotion or fatigue.
What Should Hallucination Testing Measure?
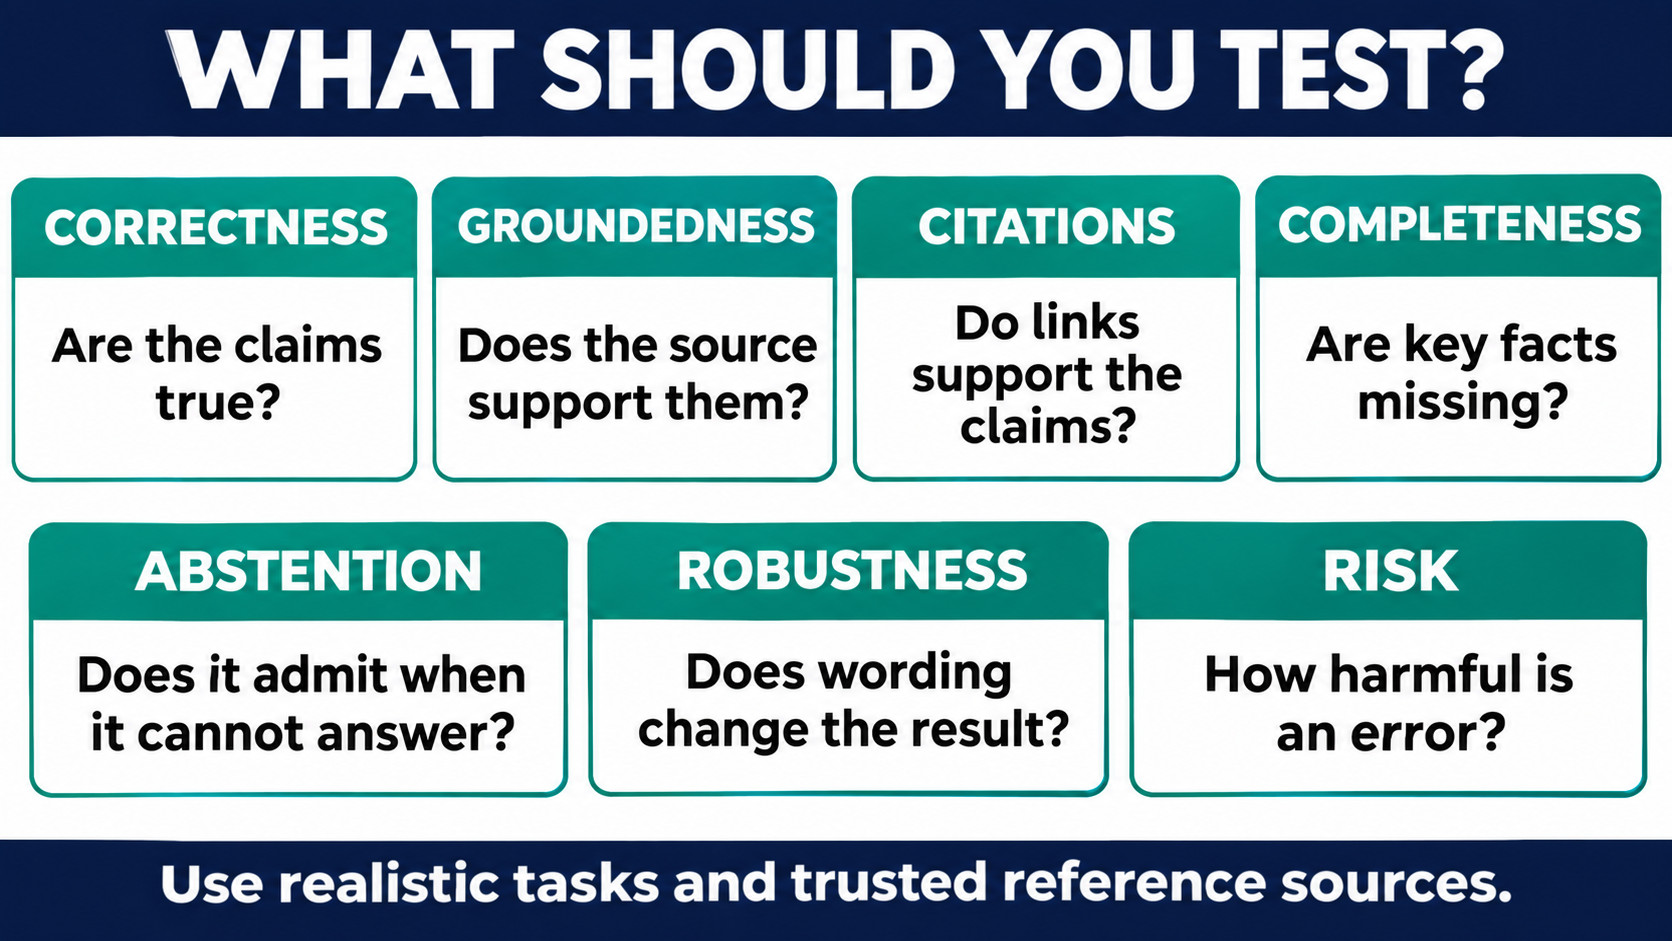
- Claim correctness: Are the material claims factually correct?
- Groundedness: Does the supplied source support each claim?
- Citation accuracy: Do cited sources exist and support the nearby statements?
- Completeness: Did the answer omit a qualification or relevant evidence?
- Abstention: Does the system say it cannot answer when evidence is missing or the question is outside scope?
- Robustness: Do small changes in wording or context cause unsupported claims?
- Risk: How harmful would the error be in the actual workflow?
Benchmarks such as TruthfulQA and FActScore can inform evaluation, but they do not replace testing with representative prompts and trusted sources. FActScore, for example, breaks long-form responses into individual claims and assesses what proportion are supported by a reliable knowledge source. These checks are part of a broader LLM testing strategy that evaluates a model’s responses across realistic tasks and inputs.
Detecting AI Hallucinations
How do systems detect and flag false outputs?
- Confidence Scoring: To enable systems to detect low-confidence responses, modern LLMs are increasingly estimating their internal uncertainty.
- Retrieval-augmented Generation (RAG) Validation: Documents that have been collected need to be compared to the results.
- Checking Consistency: Validating for agreement by utilizing multiple models or by iteratively prompting the model.
- Formal Verification: Symbolic solvers validate the results for logical or mathematical tasks.
- Human-in-the-loop QA: Necessary for enterprise, legal, and healthcare use cases.
Read: How to Keep Human In The Loop (HITL) During Gen AI Testing?
Reducing AI Hallucinations in Production
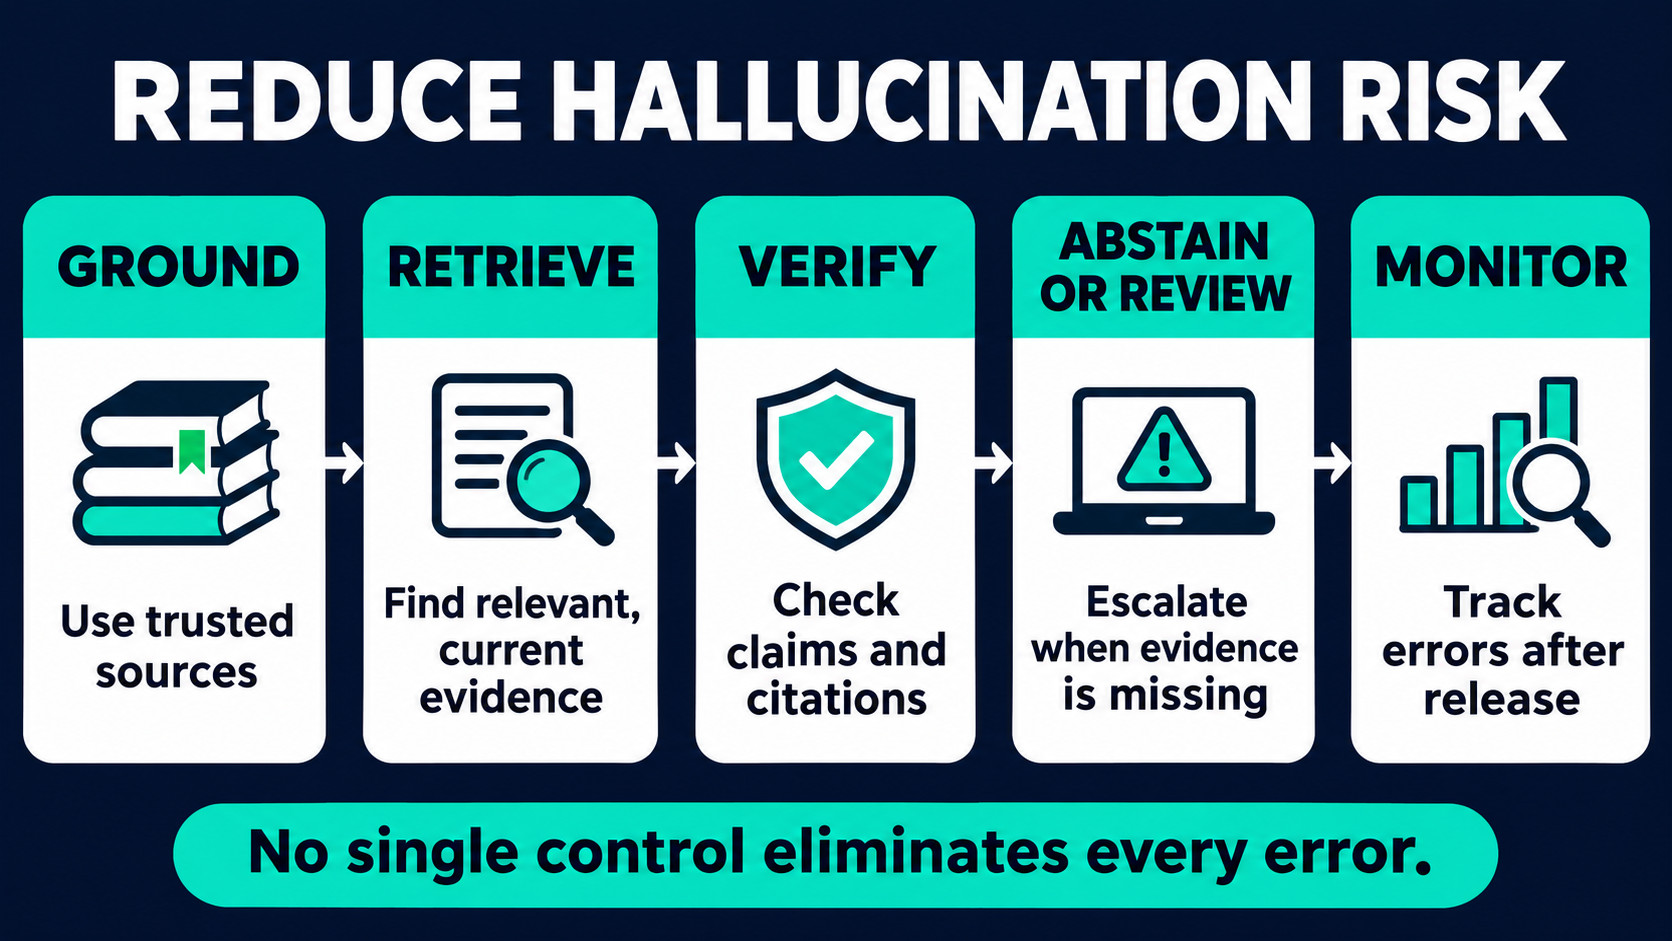
- Grounding the Model: This means connecting LLMs to:
- structured databases
- search tools
- verified knowledge stores
- Retrieval-Augmented Generation (RAG): It is a common method for reducing hallucinations, which offers context from external data before the model produces a response.
- Better Training Data: Data has been cleaned, optimized, and curated, and is less ambiguous.
- Instruction Tuning: AI-generated false facts can be significantly reduced by teaching the model to admit uncertainty.
- System-level Guardrails: Rule-based systems that change or prevent responses that appear speculative, risky from a medical and legal POV, or unsupported.
- Post-generation Fact-checking: Model chains or external APIs for output verification.
- Role Prompting and Restrictions: Confabulation in LLMs is reduced by clearly defined roles (e.g., “Answer only using the offered context”).
- Enterprise hallucination testing: Nowadays, a lot of organizations execute structured tests:
- Prompt-adversarial tests.
- Perturbation tests.
- Accuracy standards.
Read: What is Adversarial Testing of AI?
How testRigor Helps Reduce AI Hallucinations
testRigor lets teams spot fake AI responses using automation for AI-powered processes. Instead of complex scripts, you write tests in plain English. So, checking if outputs are correct becomes quick and straightforward. It flags defects early, while keeping an eye on how things work in real-world settings outside the lab. Tests don’t break easily, need little maintenance, and give clear outcomes. It helps organizations keep live AI accurate, realistic, and trustworthy by leveraging AI context, user intent, Vision AI, NLP, and other advanced AI algorithms. Testing AI-powered features is part of the broader practice of AI in software testing, where teams assess how AI behaves within real applications.
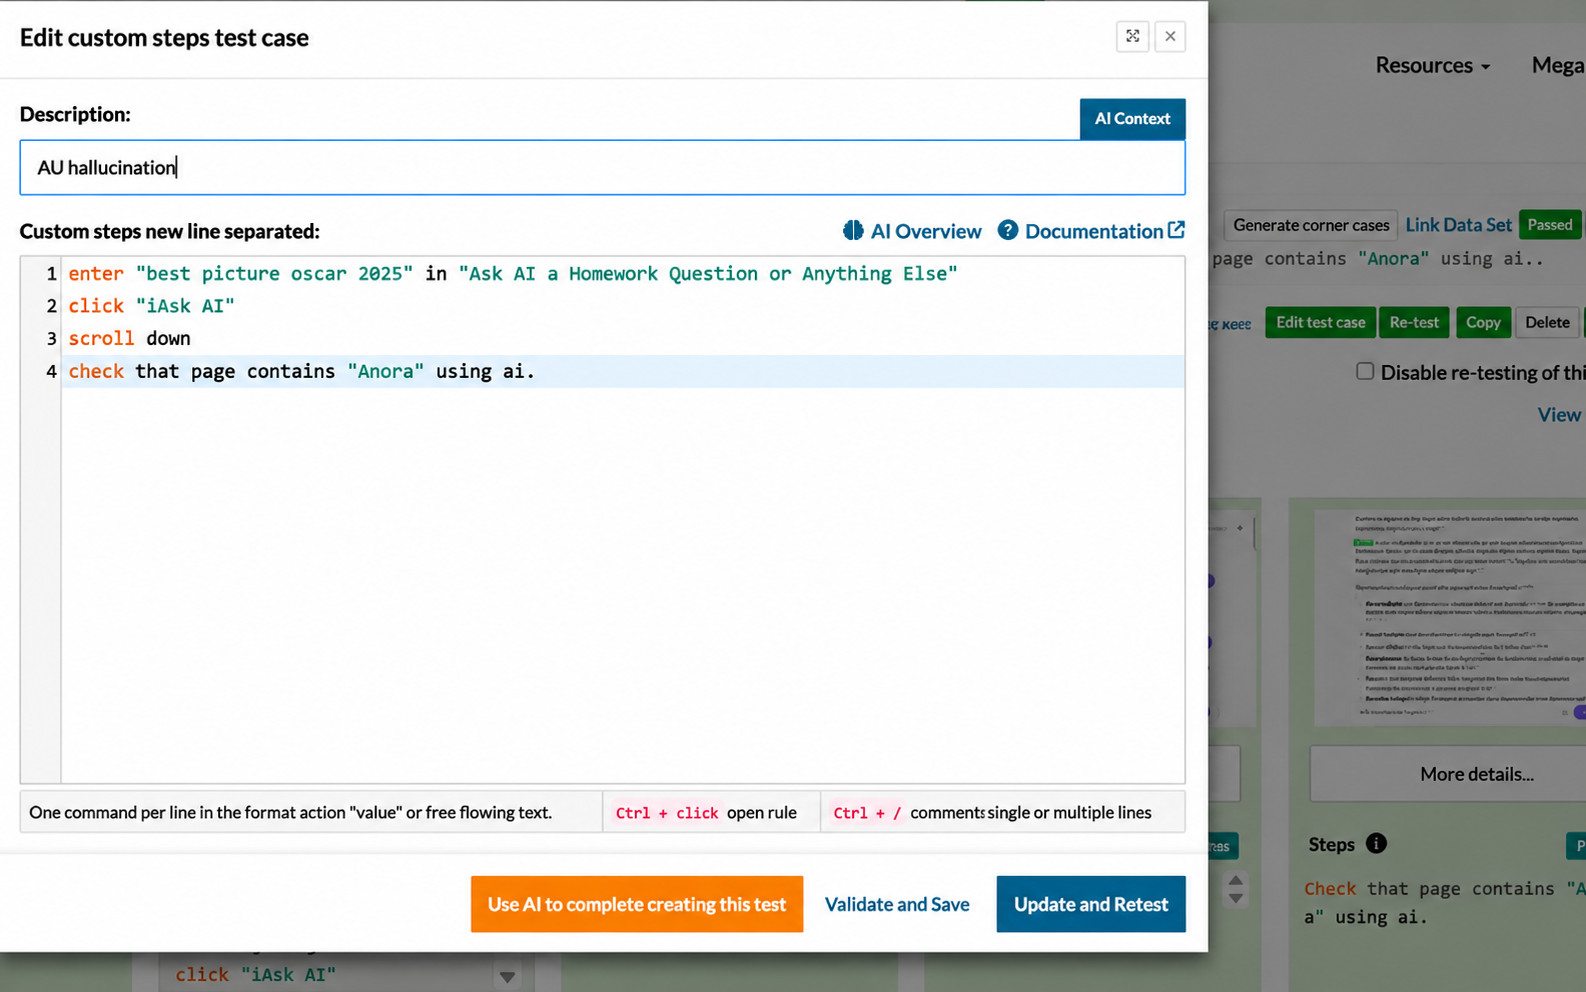
Test Case 1: Let us check an AI agent with testRigor to see if it knows which film won the most recent Oscars (2025).
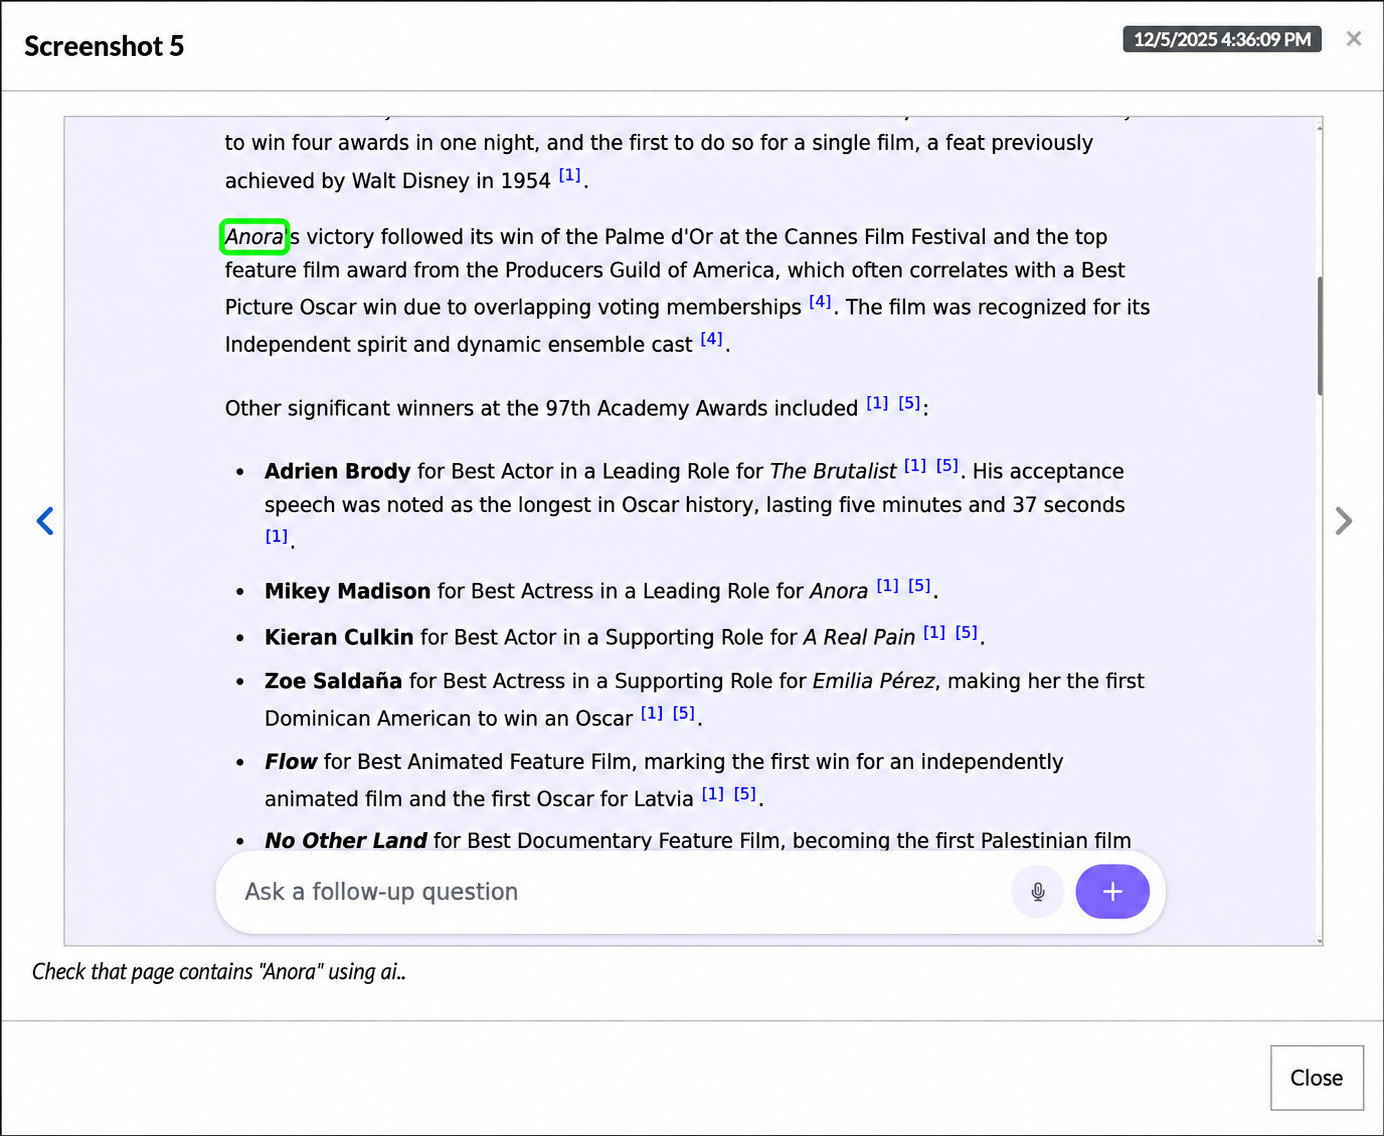
The AI agent shows the right answer, i.e., “Anora”. testRigor recognizes it using AI and marks the test “Pass”.
Test Case 2: Let us use testRigor to see if the answer is right even if the question is changed (same context, different phrasing).
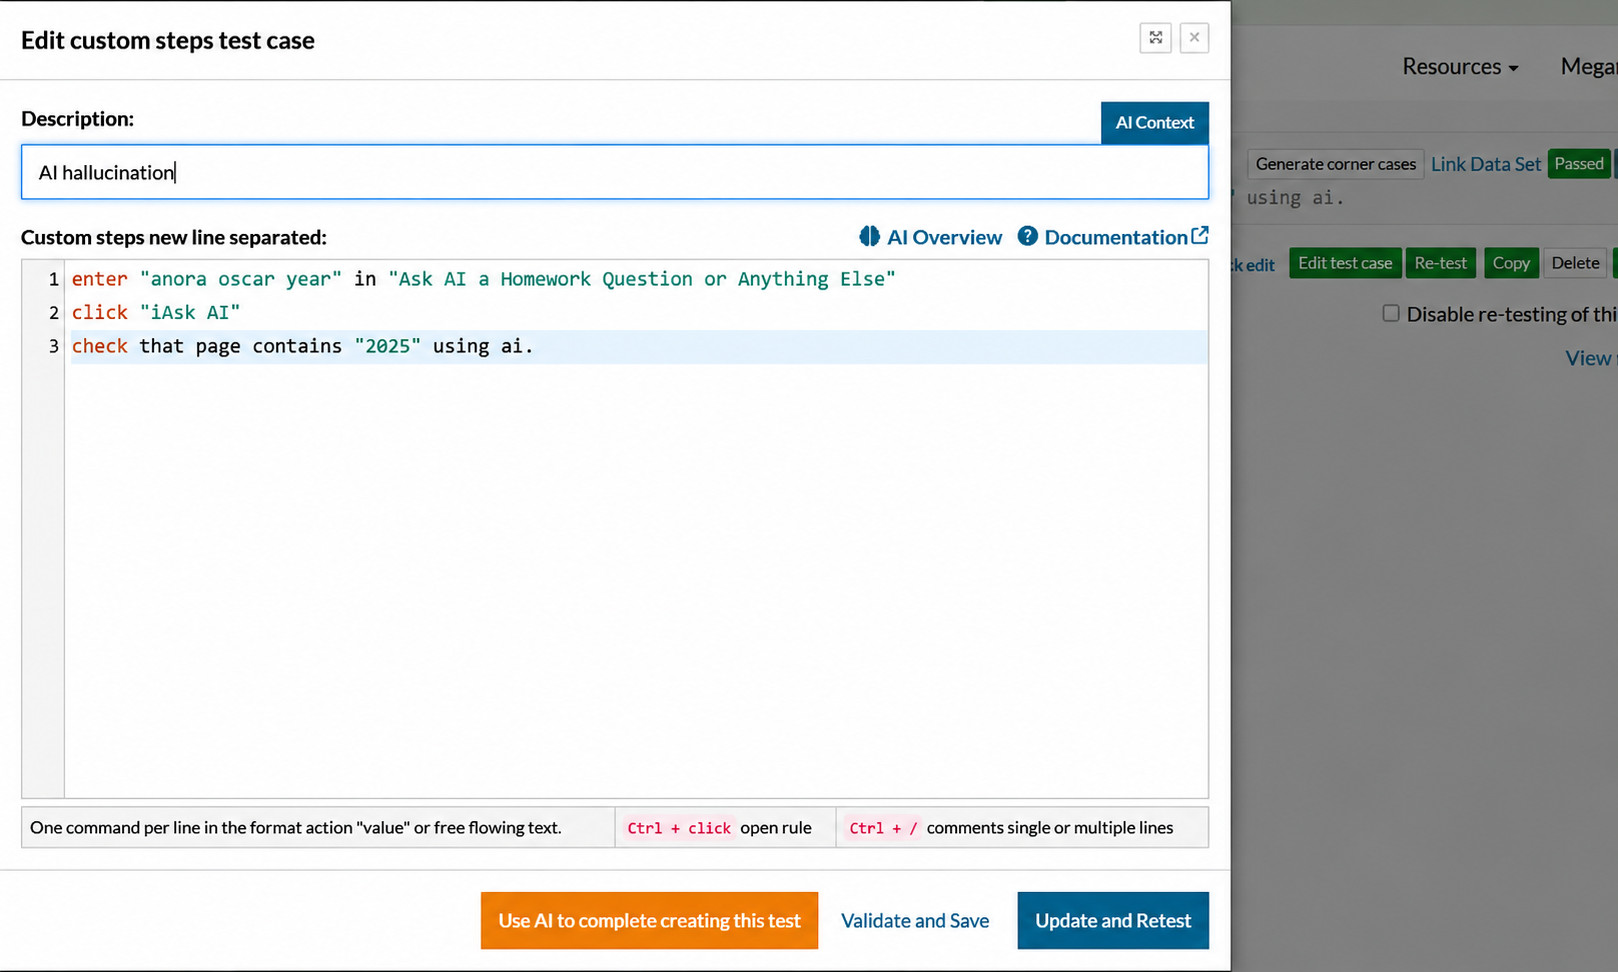
Again, the AI agent displays the year it won the Oscar correctly, and testRigor recognizes it and marks the test as “Pass”. However, if the AI agent had shown the wrong result, testRigor would have recognized that using AI. testRigor can easily identify positive/negative statements, false/true statements, user intent, complex images, graphs, and other AI features.
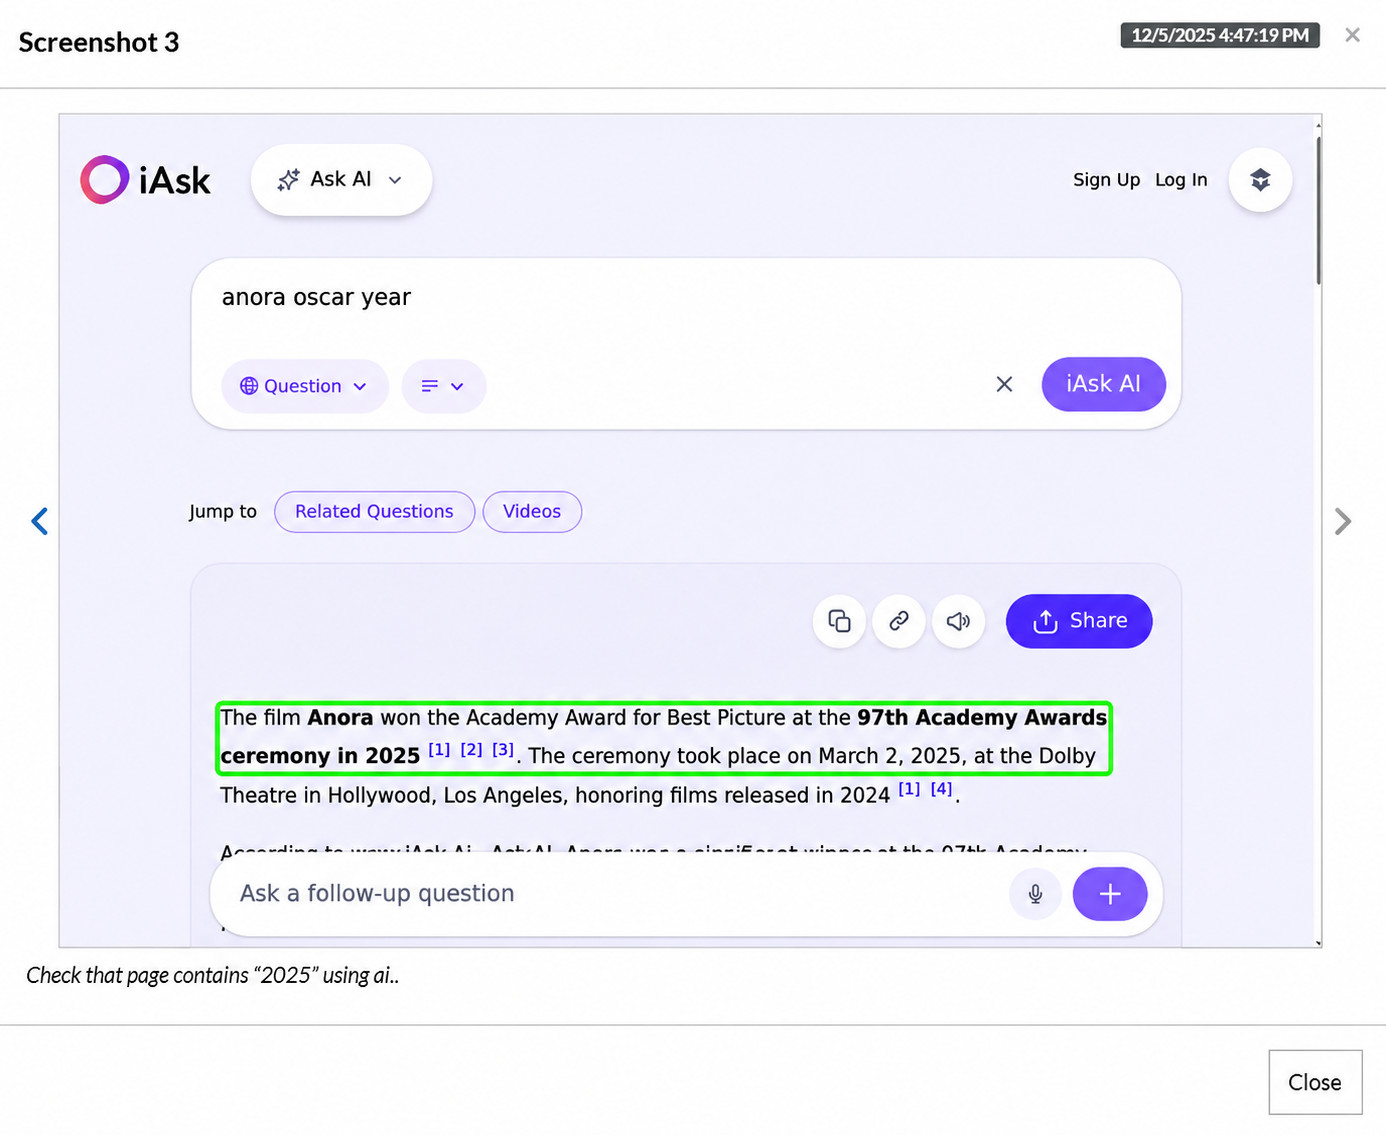
Result: It proves that different questions on the same topic yield the right answers, proving that AI was not hallucinating. testRigor’s plain English commands make it easier to test different scenarios without complicating the test case.
Troubleshooting AI Hallucinations
- Was the prompt ambiguous or leading? Make it more precise. Read more: Prompt Engineering in QA and Software Testing.
- Did the query fall outside the knowledge scope of the model? Add guardrails to encourage refusals.
- Did the model lack grounding? Connect it to knowledge bases or tools.
- Was multi-step reasoning used in the output? Make use of verified modules or chain-of-thought hiding.
- Does the domain present a major risk? Introduce workflows that are human-reviewed.
Even for complex enterprise deployments, hallucination reduction becomes feasible with the right architecture.
What’s Next in Hallucination Research and Evaluation?
One active direction is evidence traceability: recording which source supports each important claim and making that relationship auditable. NIST’s 2026 work on evaluation probes for agentic AI describes evaluating factual claims against trusted corpora and producing trails that connect claims to evidence.
Other areas include better retrieval and verification, more reliable abstention, domain-specific evaluation sets, and improved monitoring after deployment. These techniques may strengthen reliability, but teams still need to test the complete application with realistic inputs and consequences in mind.
Does AI Hallucinate or Confabulate?
- The user-facing experience: confident, inaccurate outputs that seem real are captured by AI hallucinations.
- The mechanism, which is probabilistic gap-filling based on how neural networks generate text, is captured by AI confabulation.
Teams can generate more efficient hallucination guardrails, expect reliability issues, and design better systems by understanding the difference. The proper combination of model architecture, system-level restrictions, data grounding, and human monitoring can decrease, detect, and prevent hallucinations, even though they may never fully disappear.
Our vocabulary for describing AI’s limitations evolves as AI updates. This is in addition to our methods for ensuring that generative models continue to be secure, dependable, and consistent with reality.
Frequently Asked Questions (FAQs)
- Can AI hallucinations occur in images, audio, or video?
Yes. Multimodal AI systems can make inaccurate claims about what an image shows, mis-transcribe speech, or produce an incorrect summary of a video. Creative output, such as an invented story or image, is not automatically a hallucination. The issue arises when the system presents an inaccurate or unsupported statement as factual.
- Can an AI detector reliably identify every hallucination?
No. Detectors can help flag claims that may need review, but they can miss unsupported statements or incorrectly flag accurate ones. Their results depend on the model, subject matter, and evidence available to them. For important answers, check the underlying claims against trustworthy sources instead of relying on a detector’s score alone.
- What should I do if I suspect an AI answer is wrong?
Identify the specific claim and verify it with a reliable primary source, such as official documentation, a research paper, or a relevant public record. Check that any cited source exists and supports the claim. If the answer could affect health, legal, financial, or safety decisions, consult a qualified professional before acting on it.
| Achieve More Than 90% Test Automation | |
| Step by Step Walkthroughs and Help | |
| 14 Day Free Trial, Cancel Anytime |