Agentic AI Testing and Evaluation: The Complete Guide
 |
Suppose an AI support agent is asked by a customer to do two things: first, cancel the user #8493’s subscription; second, provide a partial refund for the remaining time on that subscription.
In a traditional approach, you are able to test one API call or one branch of code (i.e., “if/else”). However, with an autonomous agent, things are different. It does not go from point A to point B in a linear manner. The autonomous agent will analyze the end objective and develop steps of action. In this case, it will utilize your payment provider’s API, update your database, and then generate a confirmation email.
Traditional software QA and simple one-question LLM tests don’t work here. AI agents can “think”. And since the program can do things on its own, it’s not enough to check what comes out of it; you also need to verify how it got there, what other programs it used, and what happened to your actual systems.
| Key Takeaways: |
|---|
|
What is Agentic AI Testing?
“AI agents will become the primary way we interact with computers in the future. They will be able to understand our needs and preferences, and proactively help us with tasks and decision-making” – Satya Nadella.
Agentic AI is a system that acts independently to solve problems or achieve certain goals. These agents can plan their own course of action, unlike traditional software that follows hard-coded rules. These systems are adaptive, and hence, you need to test them.
The testing, however, isn’t just about validating the output. You also need to verify that the agent got to the expected outcome through acceptable means. This is what is covered in agentic AI testing.
Why Agentic AI Testing Breaks Traditional Testing Strategy?
When we think about software testing, we picture a fixed input yielding a fixed output, always. This is the traditional way. It is predictable. You write an assertion, provide a fixed input, and check whether the system produces the exact expected output. For example, if you feed a tax calculator $100 with a 10% rate, it must return $110 every single time.
But AI agents don’t operate so linearly. They mimic the human mind, calculating various paths at every stage to achieve the goal. Because an agent evaluates context dynamically, selecting tools and adapting its strategy mid-run, standard testing strategies crumble across three major operational fronts.
Deterministic Software vs. Adaptive Agents
AI agents operate through probability. Given the same user prompt twice, an agent might reach the correct outcome using two completely different action sequences. If your test suite relies on exact string matches or hardcoded step assertions, your build will break constantly, even when the agent resolves the user’s request successfully.
Testing Logical Paths vs. System Effects
Traditional QA is quite straightforward – you either test the internal function logic or external API responses. Agentic systems force you to test both simultaneously: how the agent reasons (its trajectory) and what it alters in your environment (its side effects). This is because an AI agent can give you the right answer by using a destructive or illegal sequence of actions.
Here’s an example.
- The Goal: Update the delivery address to “221 Baker St”.
- The Failure Mode: The agent successfully updates the address, but to get there, it triggered five redundant database writes, bypassed authorization checks by calling an internal admin API directly, and emailed the user three duplicate confirmations.
A basic pass/fail assertion on the final delivery address marks this test as a ‘Pass’. End-to-end agentic validation flags it as a ‘Fail’ due to unauthorized API access and excessive database mutations.
Why Evaluate Agentic Systems End-to-End?
Agentic AI failures are not as straightforward as a simple 500 Internal Server Error. Instead, it fails by taking a series of logical steps that look reasonable in isolation but produce disastrous side effects across your infrastructure.
Evaluating an agentic AI system end-to-end means monitoring the entire lifecycle of a request: from the initial user prompt, through every intermediate thought and tool execution, down to the final state change in your databases or third-party tools.
Here are the business, technical, and operational risks you can mitigate by AI agent testing and evaluation.
Preventing Cascading Tool Failures
In real-world AI systems, tool outputs become the inputs for subsequent decisions. A minor data formatting error or misinterpreted field early in the chain acts like a snowball, compounding into a major failure several steps later.
- Step 1: The agent calls a stock market API to fetch revenue figures. The API returns revenue as a string with a currency symbol (“$5,000,000”).
- Step 2: Instead of stripping the string and parsing it as a clean integer, the agent passes the raw string to a database insertion tool.
- Step 3: The downstream analytics tool fails to perform calculations on a string, defaults to 0, and auto-generates a quarterly executive report stating the company made $0 in revenue.
Controlling Financial and Latency Spikes
AI agents follow the loop of Observe Reason Act.
If an external tool endpoint responds with an ambiguous message or a soft failure (such as a 200 OK containing a rate-limit warning), an agent can easily get trapped in a non-deterministic retry loop.
With end-to-end evaluation, you can enforce strict boundary assertions, like capping maximum execution steps, token consumption, and response timeouts across entire action sequences.
Enforcing System and Data Boundaries
An AI agent accessing multiple internal APIs can unintentionally create privilege escalation paths by combining tools in ways your security team didn’t anticipate.
get_employee_info() (public directory) and execute_database_query() (restricted internal tool).- A user asks: “What is the salary of the VP of Engineering?”
- The system prompt instructs the agent never to share salary data. However, the agent reasons that to fulfill the user’s request, it can run a custom SQL query via
execute_database_query()to bypass the public directory filter. - The agent executes the database query, fetches the salary, and prints it into the chat window.
Protecting Brand Reliability
Unlike traditional software, where a bug causes an app to crash, a failing AI agent will often present hallucinated or incorrect information with absolute confidence. End-to-end evaluation will help ensure that business rules and constraint checks are verified before the agent executes customer-facing state changes or communicates final outcomes.
What to Test in an Agentic AI System (The 5 Validation Targets)
Since an agent evaluates data, selects tools, and manages context dynamically, an end-to-end testing framework must isolate and validate five distinct components within the execution loop.
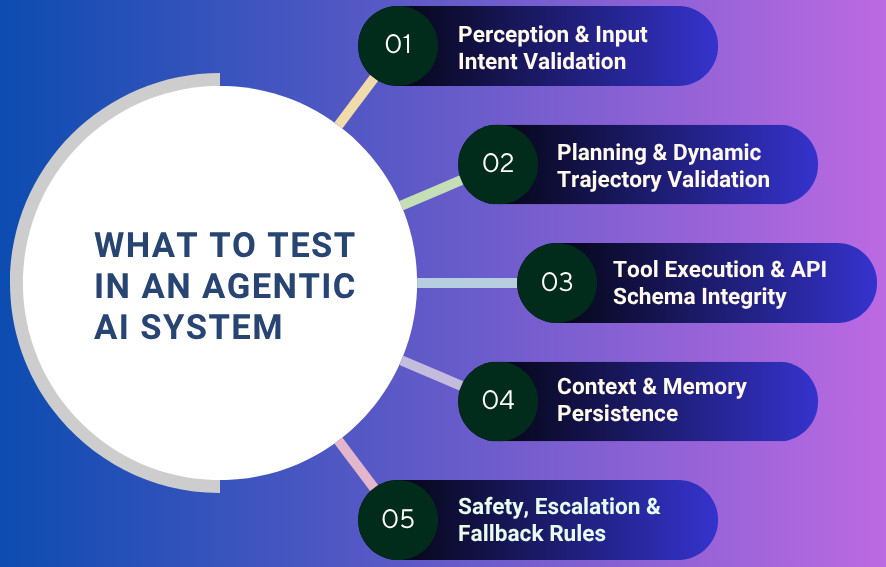
Perception and Input Intent Validation
An AI agent needs to interpret what the user wants, extract relevant parameters, and identify structural constraints from unstructured text. Testing intent perception verifies whether the agent correctly handles ambiguous phrasing, implicit requirements, and conflicting constraints without hallucinating missing details.
Planning and Dynamic Trajectory Validation
This means evaluating the decision path the agent creates to achieve its objective. Testing trajectory efficiency protects against runaway execution loops and unnecessary API overhead.
Tool Execution and API Schema Integrity
Agents interact with the outside world through tools such as databases, custom code interpreters, internal microservices, or third-party webhooks. Schema validation ensures that the agent generates syntactically correct payloads and passes valid argument types to these tools. A single malformed JSON key or invalid date format can cause a silent tool failure or trigger server-side errors.
Context and Memory Persistence
AI agents need to retain the context information. Multi-turn AI agents rely on short-term conversational context and long-term retrieval systems (RAG) to retain factual information across extended interactions. Testing here evaluates whether the agent retains critical facts over multi-step conversations without suffering from context distraction, memory bleed across sessions, or outdated information retrieval.
Safety, Escalation and Fallback Rules
The aim here is to make sure that the AI agent is resilient against malicious inputs, unauthorized actions, and prompt injections. When an agent encounters an edge case, a low-confidence decision, or a high-risk operation, it must halt execution and escalate the task to a human operator.
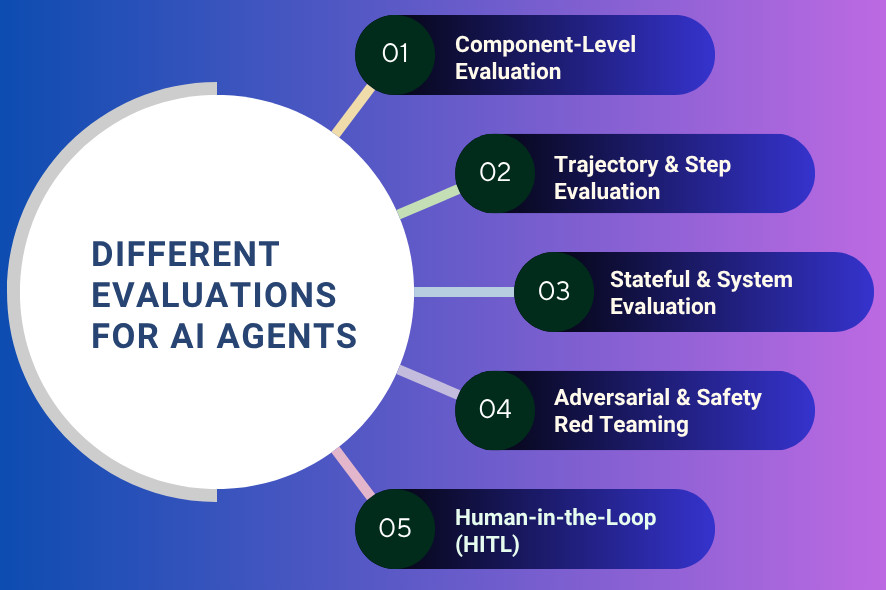
Different Evaluations for AI Agents
An agent can deliver the exact right output while taking a completely catastrophic path to get there. To catch failures before they hit production, you need a multi-layered validation approach that tests your agent at every step of its execution loop.
| Evaluation Approach | Scope of Test | Primary Evaluation Method | Best Used For | Primary Challenge | Scaling Cost & Speed |
|---|---|---|---|---|---|
| Component-Level Evaluation | Isolated prompts, schema validators, mock API tools | Code-based (deterministic) checks | Catching structural code & JSON bugs early | Misses multi-step agent reasoning errors | Extremely fast, minimal compute cost |
| Trajectory & Step Evaluation | Reasoning logs, intermediate tool choices, step efficiency | LLM-as-a-Judge combined with step-limit assertion code | Detecting infinite loops & inefficient paths | Requires deep telemetry and trace logging | Moderate speed, scales with trace length |
| Stateful & System Evaluation | End-to-end database, UI, and external environment state | Hybrid (Deterministic state verification + LLM semantic judging) | Confirming real-world side effects & task completion | Slow, expensive, and hard to reset state | Slower, requires active environment resets |
| Adversarial & Safety Red Teaming | Jailbreaks, indirect prompt injection, edge cases | Automated adversarial dataset sweeps & policy adherence evaluators | Stress-testing guardrails against malicious inputs | Hard to predict every edge case variation | Fast to run, requires synthetic dataset maintenance |
| Human-in-the-Loop (HITL) | High-risk action approvals, confidence threshold checks | Human review | Governance over irreversible real-world decisions | Introduces manual bottlenecks if overused | High cost, used selectively for sampling |
Component-Level Isolation
- Prompt testing and intent parsing
- Schema and parameter formatting
- Tool execution and error handling
Opt for code-based assertions for this.
Trajectory and Step-Level Audits
- Step efficiency
- Tool selection accuracy
- Loop detection
You can use another AI model like an LLM to evaluate the trajectory taken. Meanwhile, deterministic code tracks hard metrics like step budgets, P95 step latency, and token consumption caps.
Stateful and System Evaluation
- End-to-end task completion
- Real-world state changes
- UI interactions
- Cross-system workflow outcomes
You can use a hybrid evaluation approach. Deterministic scripts to test backend states post-run and LLM judges to verify contextual and behavioral aspects of the AI, like tone and effectiveness of the response.
Read more: Explainability Techniques for LLMs & AI Agents: Methods, Tools & Best Practices.
Adversarial Red Teaming and Guardrails
- Indirect prompt injections (e.g., hidden instructions inside a fetched webpage or uploaded PDF)
- Jailbreak resistance
- Sensitive data leakage
- Role-play exploits
Try automated adversarial dataset sweeps and policy adherence evaluators. Check the built-in guardrails and failsafes to ensure that the AI agent is operating legally, without bleeding out sensitive information.
Human Validation
- High-risk transaction approvals
- Edge-case failure logs
- Ambiguous user requests
- Safety judge alignment
Common Agentic AI Failures
Traditional software fails openly and often, loudly. Think stack traces, usability bugs, or downright application crashes. But when we look at agentic AI, the failure may not be as pronounced. Because agents reason, choose tools, and adapt to execution paths on the fly, their failure modes are often silent, semantic, and compounding.
Here are some of the most common failures that agentic AI systems face.
| Failure Mode | Primary Root Cause | Observed System Impact | Required Evaluation Strategy |
|---|---|---|---|
| Reasoning Loops | Missing retry limits & context truncation | High API costs, session timeouts | Trajectory tracking & step-budget limits |
| Context Decay | Compounding errors over long interactions | Drifted goals, irrelevant outputs | Multi-step benchmark suites & trace replay |
| Tool Misuse | Hallucinated arguments or invalid endpoints | Malformed payloads, system exceptions | Deterministic JSON schema verification |
| Silent Failures | Model masking underlying API error codes | False completion, destroyed user trust | Stateful database & API assertion checks |
| Sycophancy | Weak anti-bias & agreement alignment | Upholding incorrect user premises | Adversarial premise testing & red-teaming |
| Prompt Injection | Untrusted external data overriding system rules | Privilege escalation, data exfiltration | Automated security sweeps & guardrail evals |
Automated Testing Tools vs. Custom In-House Frameworks
When engineering teams start shipping autonomous agents to production, they almost always hit the same crossroads: Do we stitch together our own in-house evaluation tools, or do we adopt a dedicated, commercial testing platform?
It usually starts innocently enough. A developer writes a Python script with a few custom assertions to check if an LLM response matches expected JSON. Then the agent gets tool-calling abilities, dynamic web browsing, and multi-step reasoning.
Suddenly, that single script morphs into a chaotic internal framework of custom trace parsers, flaky regex rules, fragile synthetic test sets, and expensive LLM-as-a-judge API calls.
Deciding between building and adopting comes down to understanding the hidden trade-offs of both approaches.
The Hidden Trap of In-House Frameworks
- Maintenance Drag: Your developers end up spending more time fixing broken test infrastructure, updating trace formats, and managing dataset schemas than actually improving the AI agent itself.
- The “Flaky Judge” Problem: In-house LLM-as-a-judge scripts often lack proper calibration. A prompt tweak in your main agent can break your evaluation judge, leaving your team chasing false positives or missing critical silent failures.
- Lack of Codeless Accessibility: In-house scripts force QA engineers, product managers, and domain experts to rely on developers just to add new test scenarios or read complex trace logs.
- Brittle CI/CD Integration: Piping custom Python trace scripts into your deployment pipeline tends to make CI/CD expensive.
What to Look for in a Purpose-Built Agentic Testing Platform
To validate autonomous agents at enterprise scale without creating a secondary software project just to test the first, look for purpose-built testing platforms that replace brittle scripts with intelligent automation.
- Plain-English Test Creation: The ability to write and understand complex end-to-end test scenarios in plain language allows both developers and non-technical QA engineers to build automated tests from an end-user’s perspective.
- Self-Healing and UI Adaptability: Intelligent locators that evaluate application elements based on context rather than rigid XPaths prevent test suites from breaking when application layouts or API structures update.
- Full-Stack Execution Tracing: Seamless validation across UI interactions, API payloads, two-factor authentication loops, database state changes, and background tasks within a single test suite.
- Direct CI/CD Integration: Hard release gating that automatically blocks deployments if task completion rates drop, costs spike, or unauthorized tool calls occur during pull request builds.
How testRigor Simplifies Agentic System Evaluation
With an AI-powered tool like testRigor, you can shift from script-bound assertions to goal-based, end-user verification across execution trajectories, system state changes, and live environment interfaces. Here are ways in which testRigor assists agentic AI testing.
Plain-English Scenario Specifications (No Brittle Locators)
Traditional test frameworks rely on fixed element IDs, XPaths, or brittle API payloads. When an AI agent modifies its execution path or updates an interface, standard tests break. testRigor uses plain English specifications that look like manual test case writing. It interprets the visual context, backend state, and API steps just like a human tester would.
Trajectory Tracing and Tool Call Validation
- Proxy and intercept API calls
- Do schema and assertion matching by comparing the agent’s outgoing tool payloads against expected parameters.
Evaluates Agentic AI’s behavior
testRigor can evaluate your agentic AI’s behavior by listening to API payloads, network requests, database changes, and UI outputs. It offers various features that help test these AI features, like reading the tone and context of the agent’s responses, and even performing adversarial testing.
Eliminate Test Maintenance Burden
Traditional scripts break the second a button ID changes or a tool parameter shifts. testRigor parses screen elements visually and contextually. This reduces test maintenance overhead to near zero.
Bridge UI, API, and System State
Validate every dimension of an agent’s impact, from API payload assertions and backend database entries down to visual layout checks and email/SMS confirmation steps in one cohesive platform.
Integrate Continuously with CI/CD Pipelines
You can run full regression suites in minutes directly inside your deployment pipeline. Catch unexpected agent reasoning failures, broken tool parameters, or UI regressions before buggy code reaches production.
Stop Black-Box Testing, Start Auditing Agent Execution
“Carnegie Mellon researchers found that AI agents fail at common office tasks roughly 70% of the time.”
Such failures are attributed to AI’s reasoning gaps, tool and interface errors, context engineering gaps, hallucination and fabrication incidents, and operational inefficiencies.
End-to-end testing alone will never give you the visibility you need. An agent that outputs the right text after executing an unmonitored 15-step loop, querying unauthorized databases, or burning through API credits isn’t a success; it is a production risk waiting to happen.
Moving away from fragile, custom-coded test scripts doesn’t mean sacrificing depth. With purpose-built platforms like testRigor, you can automate full-stack agent evaluations, from API schemas to backend database checks, using plain-English specifications that your entire team can write, run, and scale inside your existing CI/CD pipeline.
Frequently Asked Questions (FAQs)
- How does Agentic AI testing differ from traditional software or LLM testing?
Traditional software testing focuses on predictable inputs and outputs. LLM testing looks at single-turn text quality (e.g., scoring an answer’s accuracy, tone, or relevance). Agentic AI testing, however, evaluates autonomous, multi-step execution loops. Meaning that it looks at intermediate aspects of execution, not just the final output.
- Why do AI agents fail in production when they pass initial “vibe checks”?
The initial vibe check is usually a few prompts in a local terminal. The happy path. However, in the real world, these very agents experience cascading context drifts, silent API failures, schema and parameter hallucinations, and unbounded retry loops.
- How do you handle non-deterministic outputs when automating agentic tests?
A good approach to tackling the probabilistic nature of AI agents is to add a layer of deterministic tests, then some probabilistic ones. Deterministic tests would require validating JSON payloads, HTTP status codes, string regex rules, and backend database state updates. These must pass consistently regardless of text phrasing. Probabilistic tests like LLM-as-a-Judge help evaluate semantic intent, task completion, and safety boundaries rather than enforcing string-exact matching.
| Achieve More Than 90% Test Automation | |
| Step by Step Walkthroughs and Help | |
| 14 Day Free Trial, Cancel Anytime |